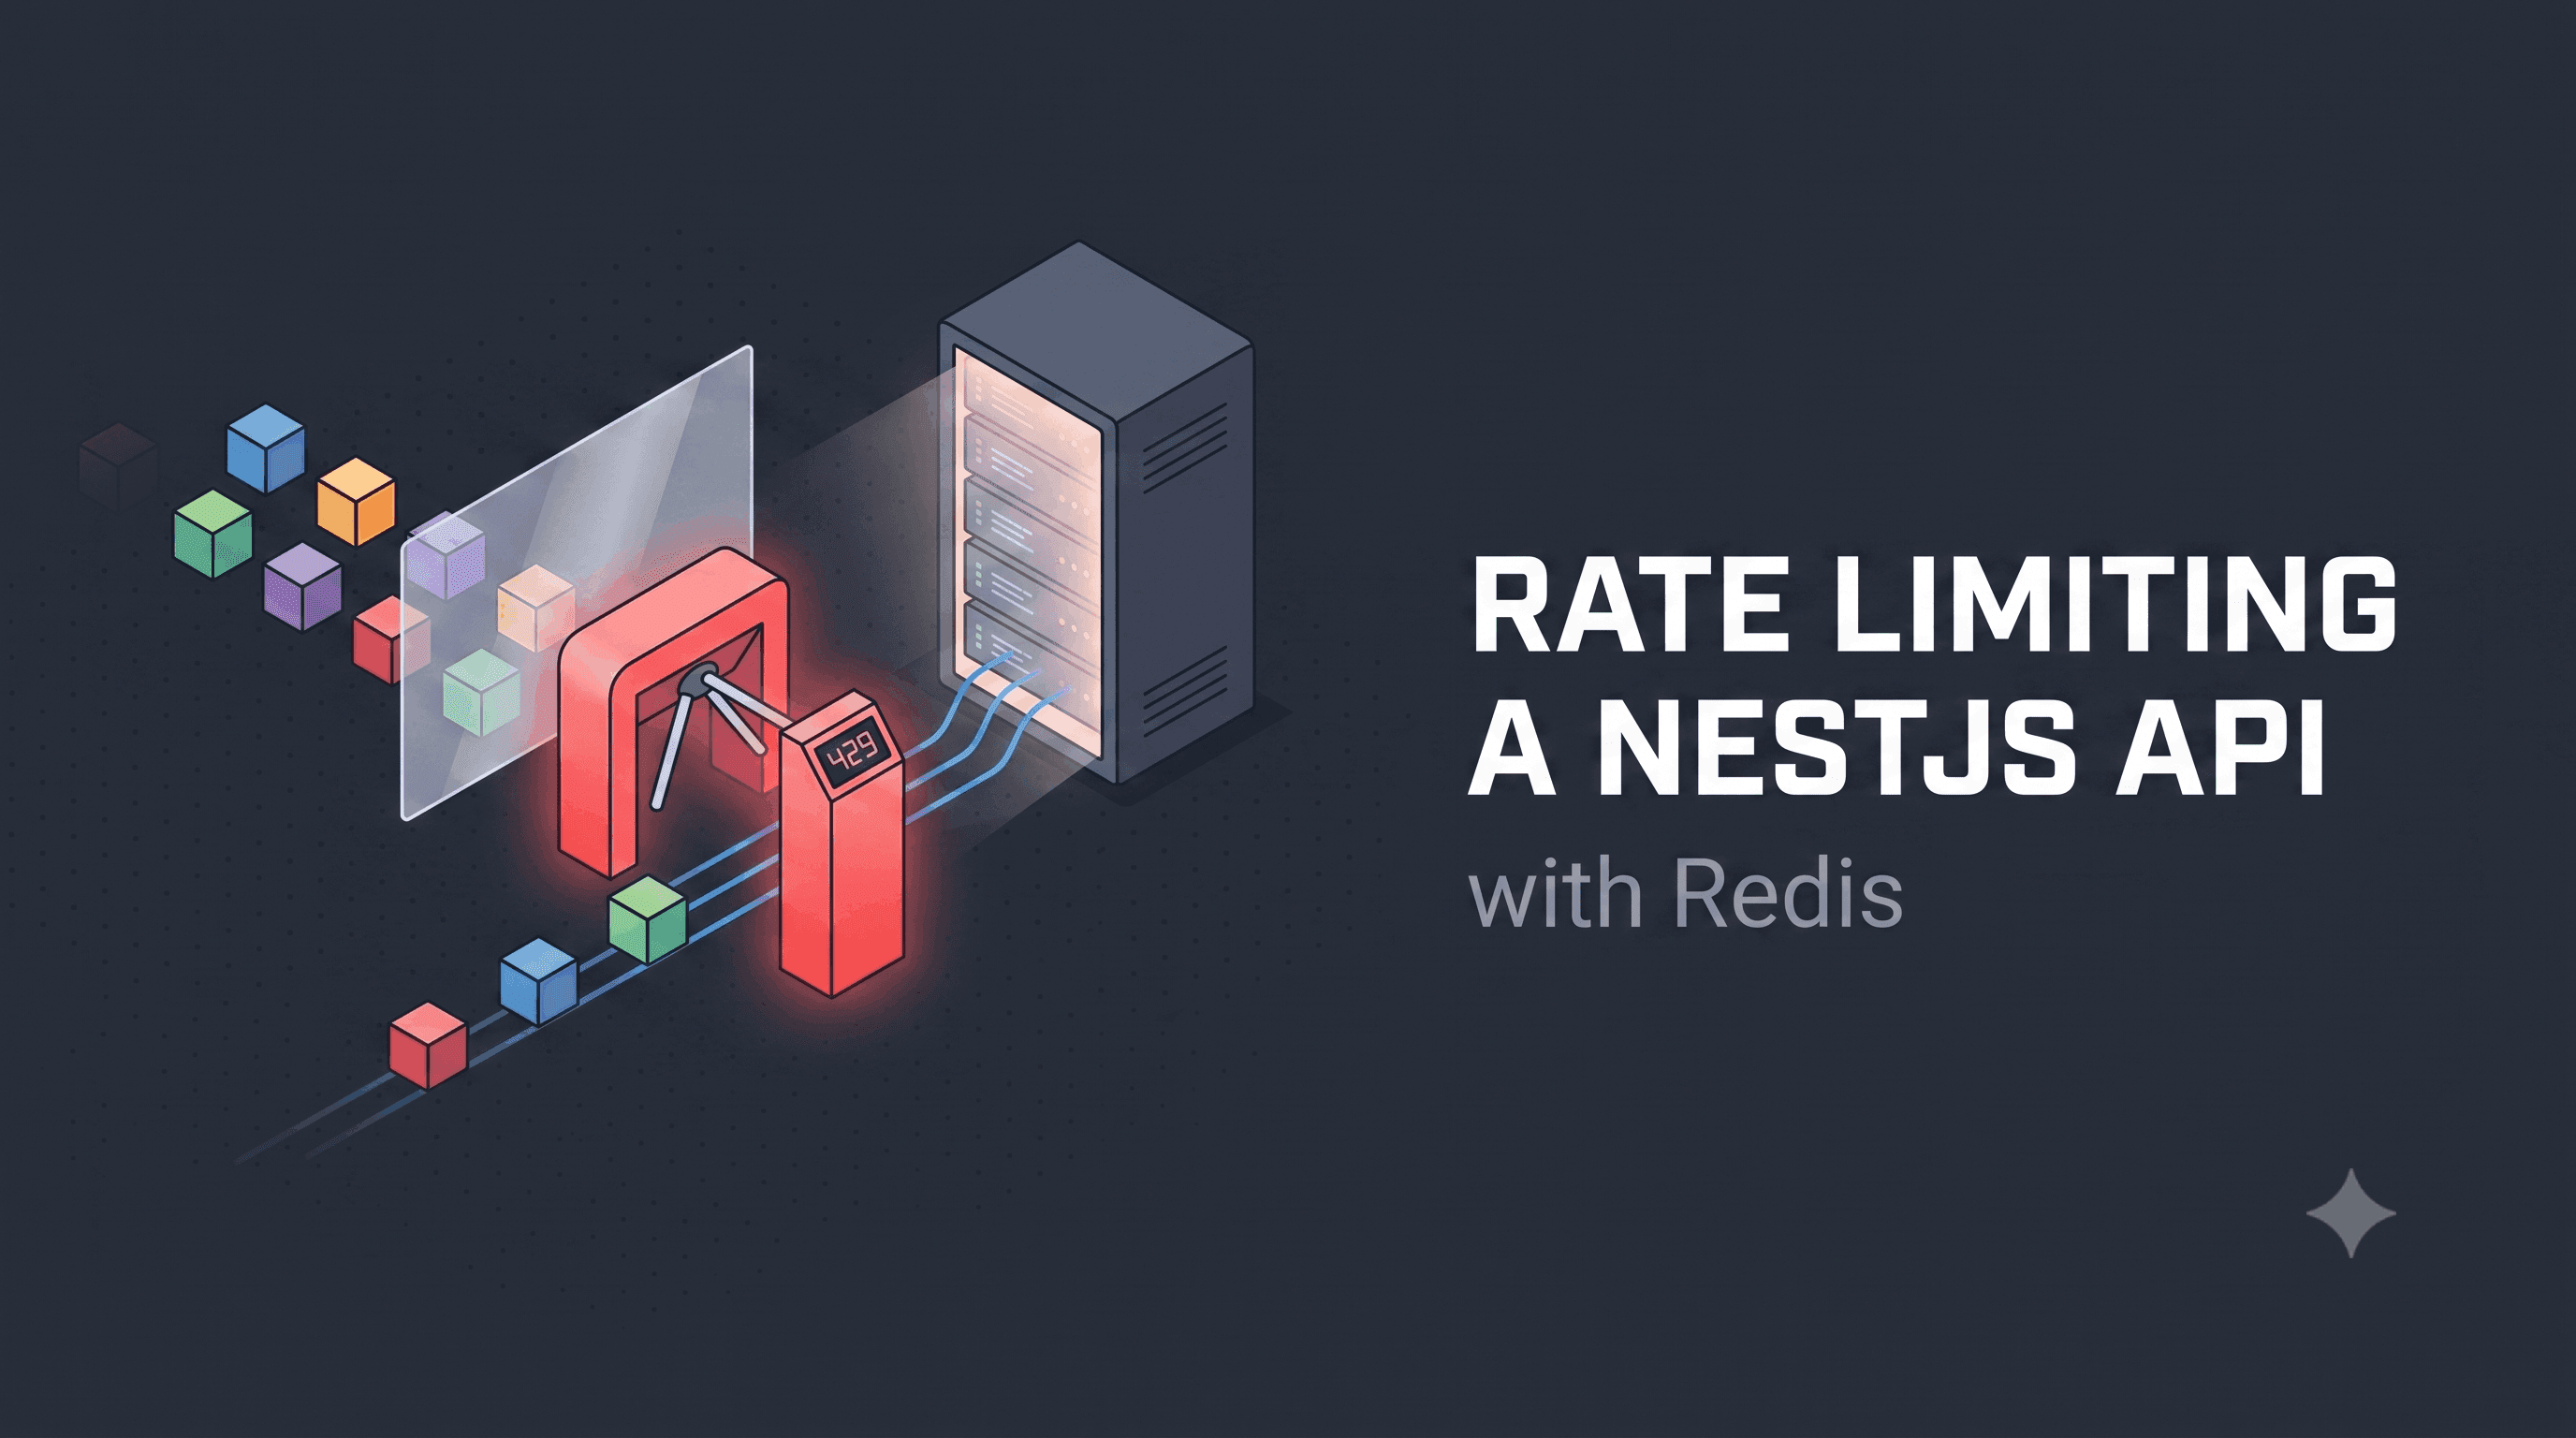
An in-memory rate limiter works perfectly in local development and then quietly stops working the moment the API runs behind a load balancer with more than one instance — each instance counts requests independently, so a limit of 100 requests per minute becomes 100 times however many instances are running. Redis fixes this by giving every instance the same counter.
A shared store is not optional at scale
@nestjs/throttler ships with an in-memory storage adapter by default, which is fine for a single-instance API or local development, but swapping in @nest-lab/throttler-storage-redis is a configuration change, not a rewrite — the guard logic stays identical, only where the counters live changes.
ThrottlerModule.forRootAsync({
  imports: [ConfigModule],
  inject: [ConfigService],
  useFactory: (config: ConfigService) => ({
    throttlers: [
      { name: 'default', ttl: 60_000, limit: 100 },
    ],
    storage: new ThrottlerStorageRedisService(
      new Redis(config.getOrThrow('REDIS_URL')),
    ),
  }),
}),
Different routes need different limits
A global limit sized for a login endpoint (a handful of attempts per minute, to slow down credential stuffing) is far too strict for a product listing endpoint that a single page load might call several times. @Throttle() overrides the default per-route, and combining a strict limit on auth routes with a looser one everywhere else is usually the whole policy a typical API needs.
- Key the limiter by user id for authenticated routes, not just by IP — a shared office or VPN IP should not throttle every employee together.
- Apply a stricter limit specifically to
/auth/loginand/auth/register— these are the routes brute-force and credential-stuffing attacks actually target. - Return
Retry-Afterin the 429 response so a well-behaved client backs off instead of hammering the endpoint immediately again. - A CDN or reverse proxy rate limit (Cloudflare, an API gateway) is a first line of defense, not a replacement for application-level limits — it stops the crudest floods before they reach the app at all.
- Skip throttling for webhook endpoints called only by trusted, already-authenticated gateways — the limiter is meant for untrusted traffic.
Per-route overrides, concretely
The decorator-based override keeps the strict policy visible right on the controller method instead of buried in a central config file that nobody remembers to check when adding a new sensitive route.
@Throttle({ default: { limit: 5, ttl: 60_000 } })
@Post('login')
async login(@Body() dto: LoginDto) {
  return this.authService.login(dto);
}

@SkipThrottle()
@Post('webhooks/vnpay')
async handleWebhook(@Body() body: VnpayWebhookDto) {
  return this.paymentsService.handleWebhookEvent(body);
}
Rate limiting slows down abuse; it does not stop a determined attacker with a botnet of rotating IPs. Treat it as one layer among several — account lockouts after repeated failures, CAPTCHA on suspicious patterns, and monitoring — not the entire defense.
Different limits for authenticated users and anonymous traffic
A single global limit forces an uncomfortable trade-off: loose enough for a logged-in, trusted user browsing normally, and it is far too loose to slow down an anonymous bot scraping the catalog from a rotating IP pool. A custom ThrottlerGuard that reads the request context and picks a different limit for authenticated versus anonymous traffic resolves the trade-off instead of splitting the difference badly for both.
@Injectable()
export class ContextAwareThrottlerGuard extends ThrottlerGuard {
  protected async getTracker(req: Record<string, any>): Promise<string> {
    // Authenticated: key by user id, so a shared office IP does not
    // throttle every employee together.
    if (req.user?.sub) return `user:${req.user.sub}`;
    return `ip:${req.ip}`;
  }

  protected async getLimit(context: ExecutionContext): Promise<number> {
    const req = context.switchToHttp().getRequest();
    return req.user ? 300 : 60; // requests per window
  }
}- Keying by user id also means a user switching networks (wifi to mobile data) does not lose their limit budget or get double-counted across two IPs.
- A logged-in user behind a shared corporate NAT no longer shares a limit bucket with every other employee on the same connection.
- Anonymous traffic still needs a floor strict enough to make scraping unattractive — loosening it defeats the purpose of having two tiers at all.
Responding gracefully instead of just returning 429
A bare 429 Too Many Requests with no other information leaves a well-behaved client guessing how long to wait, which often means it retries immediately and gets throttled again. Returning Retry-After and a small JSON body describing the limit lets a reasonable client back off exactly as long as necessary, and lets a frontend show a real countdown instead of a generic error toast.
@Catch(ThrottlerException)
export class ThrottlerExceptionFilter implements ExceptionFilter {
  catch(exception: ThrottlerException, host: ArgumentsHost) {
    const response = host.switchToHttp().getResponse();
    const retryAfterSeconds = 60;

    response
      .status(429)
      .header('Retry-After', String(retryAfterSeconds))
      .json({
        statusCode: 429,
        message: 'Too many requests. Please slow down.',
        retryAfterSeconds,
      });
  }
}
A frontend that reads retryAfterSeconds and disables the submit button with a visible countdown turns an opaque failure into an understandable, temporary state — the same UX principle as a form showing "resend code in 30s" instead of just silently rejecting an early resend click.
Limits are a product decision as much as a security one
A limit set purely from a security threat model — "how many login attempts constitutes an attack" — can accidentally lock out a legitimate user on a flaky mobile connection who retries a slow request a few times in quick succession. Involving whoever owns the product experience in setting the actual numbers, not just the engineering team defending against abuse, usually produces a limit that stops real attacks without becoming a support ticket generator for real users.
Logging every throttled request with enough context to distinguish "one user hammering an endpoint" from "many different users all hitting a limit that is simply too strict" is what turns a limit from a guess into something that can actually be tuned with evidence over time.
It is worth distinguishing throttling (slowing a client down) from blocking (refusing a client entirely) — a rate limiter answers "how many requests per window," while a web application firewall or an IP denylist answers "should this source be talking to us at all." Conflating the two in one mechanism usually produces a limiter tuned too aggressively for the common case in an attempt to also catch the rare malicious one, when a second, separate layer handles the malicious case far better without punishing everyone else.
One more distinction worth making explicit in the guard's documentation: a limit measured "per window" resets abruptly at the window boundary, which lets a client burst up to twice the intended rate right across that boundary, while a sliding-window or token-bucket implementation smooths that out at the cost of slightly more bookkeeping in Redis. For most APIs the simpler fixed-window approach is good enough, but it is worth knowing which one is actually running before promising a precise rate guarantee to an API consumer.
A final practical note: expose the current limit and remaining quota to API consumers via standard X-RateLimit-Limit and X-RateLimit-Remaining response headers on every request, not only on the one that finally gets throttled. A well-behaved client that can see it is approaching a limit can back off proactively, turning a hard 429 into a rare event instead of the primary way a client discovers the limit exists at all.
Conclusion
Rate limiting only does its job once every instance of the API agrees on the count, which means a Redis-backed store is not an optimization but a correctness requirement for anything running behind a load balancer. Layer a strict limit on auth routes, a looser default everywhere else, and key by user id wherever a request is authenticated.